AI, Full stackNov 2026 - PresentWeb app
SpeakUp - AI Speaking Coach
AI speaking coach that analyzes audio and transcripts to give timestamped feedback on how you speak.
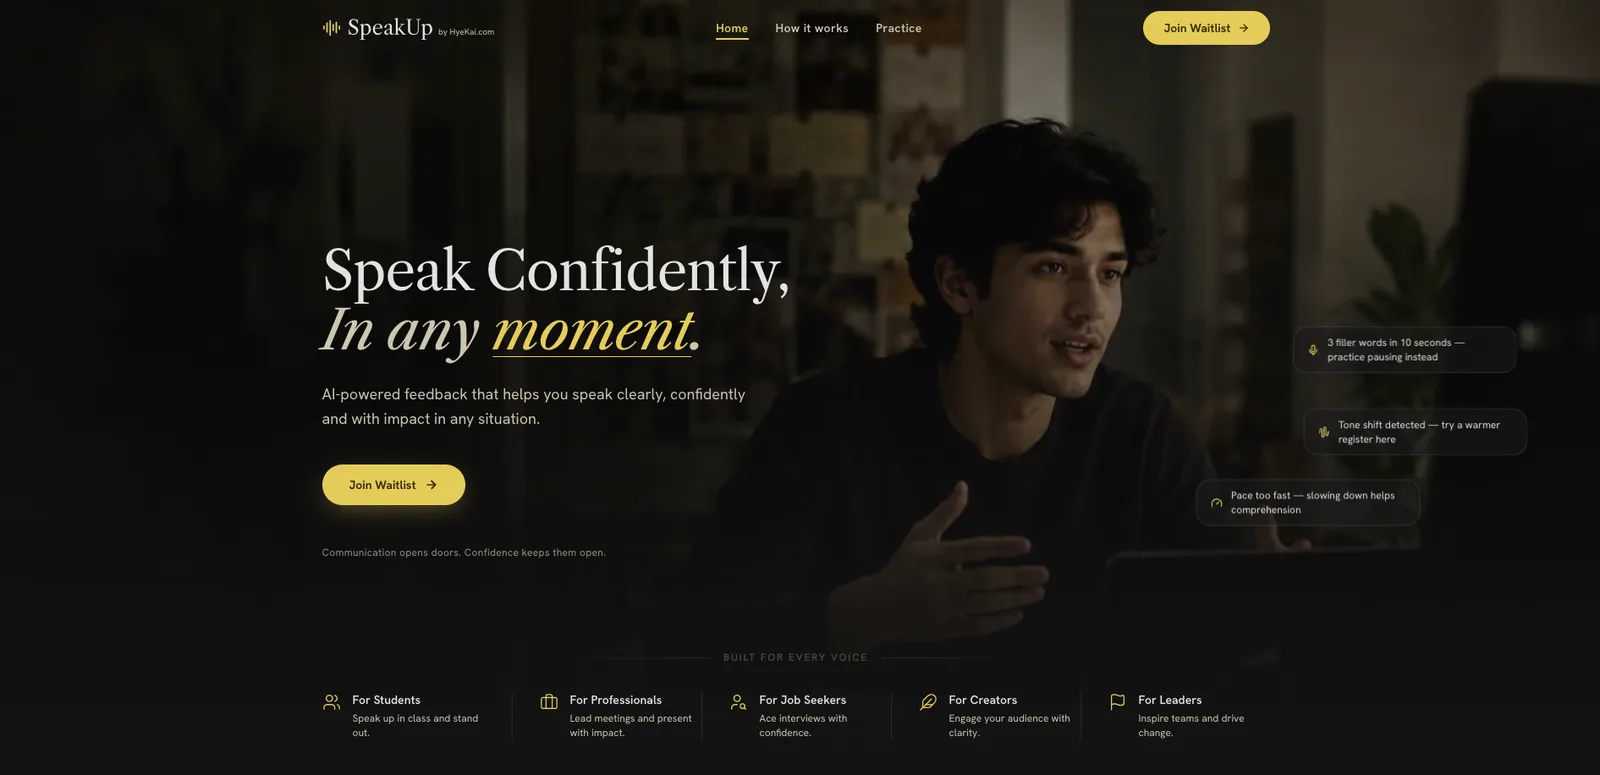
SpeakUp home page
The problem
Many people have good ideas but freeze, ramble, or lean on fillers when they have to speak in interviews, client calls, or on stage. Grammar checkers and generic scores don't help: they can't say where a speech lost its listener or why, so practice rarely turns into improvement.
The result
Designed a three-dimension speech evaluation framework (Delivery, Language & Framing, Content & Substance) and shipped the SpeakUp web app and public waitlist site on top of a Modal-hosted audio-processing and LLM pipeline, built so feedback points at exact moments in a recording instead of a single vague score.
How it works
SpeakUp helps people practice, test, and improve how they speak so they sound clear, confident, and professional. A recorded answer is evaluated on three dimensions: Delivery (how it sounds), Language & Framing (the words chosen), and Content & Substance (the message), by combining audio signal processing, transcript analysis, and LLM judgement. The user-facing app is built with Next.js on Vercel; the heavy generative-AI and audio-signal-processing work runs on Modal, LLM calls go through LiteLLM, and application data lives in Neon PostgreSQL with Upstash Redis alongside it.
Key technical design points include:
- Locate → Infer → Verdict feedback: each delivery metric (pausing, thought-group phrasing, semantic emphasis, cadence) is reported as where it happened (a timestamp), why the speaker likely did it (for example a pause at a clause boundary versus one mid-verb-phrase), and whether it helped or hurt in context. That lets feedback say 'at 01:14 you paused 1.2s right before the core metric' rather than 'your pausing score is 6/10'.
- Signal processing before LLMs: pauses come from silence detection with a tunable threshold (300 ms to start), pacing from sliding 5-second tempo windows, and emphasis from pitch, energy, and vowel-duration peaks on word-aligned audio; the LLM is reserved for judgements that need language understanding.
- Pre-evaluation gateway: jitter, shimmer, harmonic-to-noise ratio, and voice energy are checked first, and if a recording is far outside normal the user is warned and must confirm before continuing, since the speech would likely be judged poorly regardless of the other metrics.
- Structured, verifiable LLM output: Language and Content metrics return typed findings (phrase ids, category, severity 1-3, the offending text checked as a substring of the transcript, and a suggested rewrite) rather than free text.
- Hybrid scoring: the LLM only picks a band (1-5) from anchored descriptors, and the 0-100 score is computed deterministically from finding density and severity, because models asked for a raw 0-100 cluster around 70-85 and give false precision; the score stays stable across reruns and is usable for tracking progress over time.
- Scored vs. non-scored signals: terminal contour (up-talk) and energy decay are tracked as indicators without being scored, while fluency events (fillers, restarts, repetitions, self-corrections) and hedging language feed the scores.
- Practice flow: a guided test flow with rules, prepare time with notes, and recording, plus practice modes (Quick Prompt, Read & Explain, Interview Simulator, Debate Arena) presented on the product site.
Tech stack
- Next.js
- React
- TypeScript
- Tailwind CSS
- Zustand
- Vercel
- Python
- Modal
- LiteLLM
- Pydantic
- Parselmouth
- Montreal Forced Aligner
- PostgreSQL (Neon)
- Redis (Upstash)
Tags
- Speech Analysis
- Audio Signal Processing
- Prosody Analysis
- Pause Detection
- Thought-Group Phrasing
- Semantic Emphasis Detection
- Forced Alignment
- Transcript Analysis
- LLM Evaluation
- Structured LLM Output
- Anchored Rubric Scoring
- Serverless Compute